Pipeline Trace Diagram
A pipeline run read into a trace - a timespan for the run, every called workflow, matrix, job and step - is written as OpenTelemetry’s OTLP/JSON, which trace viewers read, or drawn as a Gantt chart.
Reading a Run
WorkflowRunReader reads a workflow run through the GitHub REST API, using the
standard library only:
from os import getenv
from pathlib import Path
from pyTooling.GitHub.Tracing import WorkflowRunReader

reader = WorkflowRunReader("pyTooling/Actions", token=getenv("GITHUB_TOKEN"))
trace = reader.ReadRun(34937615362)      # optionally: attempt=2
trace.WriteJSONFile(Path("report/Pipeline.otlp.json"))
Inside a workflow, GITHUB_TOKEN with the actions: read permission suffices. A job can’t see itself: it is
still running when it reads the run, so a timing job depends on every other job and runs last.
A request failing transiently - HTTP 429, 500, 502, 503 or 504, a timeout, or an unreachable API - is tried again,
retries times (default: 3), after a pause of retryDelay seconds (default: 2), which doubles with every attempt
or lasts as long as a Retry-After header demands, up to a minute. HTTP 401, 403 and 404 fail at once.
WorkflowRunTrace.FromJSON does the conversion alone,
for a run and jobs that were fetched another way. It is a class method, so converting needs no reader and therefore
no token. It reads both payloads into a Pipeline - see Pipeline Run - and hands
that to FromPipeline(), which is the entry point when the model
was built elsewhere. Reading the payloads is therefore the model’s job, and a field GitHub doesn’t document raises
GitHubError - as does an answer the reader itself can’t read, so everything GitHub says
that can’t be made sense of is one exception type. A request that fails is a
RESTError, because nothing about GitHub’s answer was wrong - there wasn’t one.
Timespans and Attributes
The run becomes the trace, and every timespan below it is marked by Kind with a
member of SpanKind. Each kind is a class of its own - a
JobSpan sets ci.span.kind to job because that is what it is, and takes the
attributes of a job as parameters - so a reader states values and never a key, and a reader of another service
builds the same classes:
Kind |
Timespan |
|---|---|
|
The workflow run, from its start to its last update once it completed. |
|
A called workflow: the jobs named |
|
A matrix: the jobs named |
|
|
|
A job, from its start to its completion. |
|
A step that started, below its job. |
Every timespan also carries the attributes of OpenTelemetry’s semantic conventions for CI/CD, which
OTLP names as a namespace nested the way the keys are - so
OTLP.CICD.Pipeline.Task.Run.ID spells cicd.pipeline.task.run.id and the path
can be read to check the key. The values a result may take are Result, which are
those of the model’s Outcome, so a result is the element’s outcome. What only GitHub
reports is named the same way by GitHub, e.g.
github.conclusion beside the result it was mapped to. A job’s timespan names its runner and the labels it was
requested by, so a renderer can group waiting times per operating system, and a matrix instance additionally lists the
values it was produced for in github.matrix.dimensions.
A task is named the way GitHub reports it - Caller / Build (ubuntu-26.04) - while the timespan itself is named by
the part the model holds, so a timespan reads in the context its parents already give.
Each flavour builds itself from the model: JobSpan.FromJob takes
a Job and produces the job’s timespan, the waiting timespan in front of it, and a
timespan per step. So reading a service means mapping its model onto these classes, and everything else - the kinds,
the attribute keys, and skipping what the service doesn’t report - is
pyTooling.Tracing.CI’s.
What the payloads say is the model’s, including the two facts a timeline depends on: a group’s elements come in the order they were queued, and a job’s times contain its steps, because GitHub reports both in whole seconds and a step is sometimes reported as running outside the job holding it - see Pipeline Run.
GitHub reports timestamps in whole seconds. A step shorter than a second lasts zero seconds, and an end reported a second before its begin is moved to the begin.
Gantt Chart
pyTooling lays a trace out as a Gantt chart and draws it with matplotlib - see
pyTooling’s rendering. ciSpanFilter()
selects what a pipeline’s chart shows:
from pyTooling.Tracing.Render            import GanttLayout, ciSpanFilter
from pyTooling.Tracing.Render.Matplotlib import MatplotlibRenderer

layout = GanttLayout(trace, spanFilter=ciSpanFilter())
MatplotlibRenderer(layout).Write(Path("report/Pipeline.svg"))
A row per job, below the rows of the called workflow and the matrix it belongs to. The time a job waited for a runner is drawn in light gray in front of the time it ran, colored per runner image.
The legend carries the statistics per runner image: the number of jobs, and the shortest, average and longest waiting and running times.
The steps are left out - a pipeline of 52 jobs has hundreds of them.
excludeSteps=StepExclusion.Skippedshows the steps that ran,excludeSteps=Falseevery step. Skipped jobs are left out too, unlessexcludeSkippedJobs=False.MatplotlibRenderer(layout, collapsible=True)writes an SVG file whose rows of called workflows and jobs can be collapsed and expanded with a click.
The drawing needs the extra diagram (see Gantt Charts (Optional)). The program draws the same chart with
--gantt - see Drawing the run.
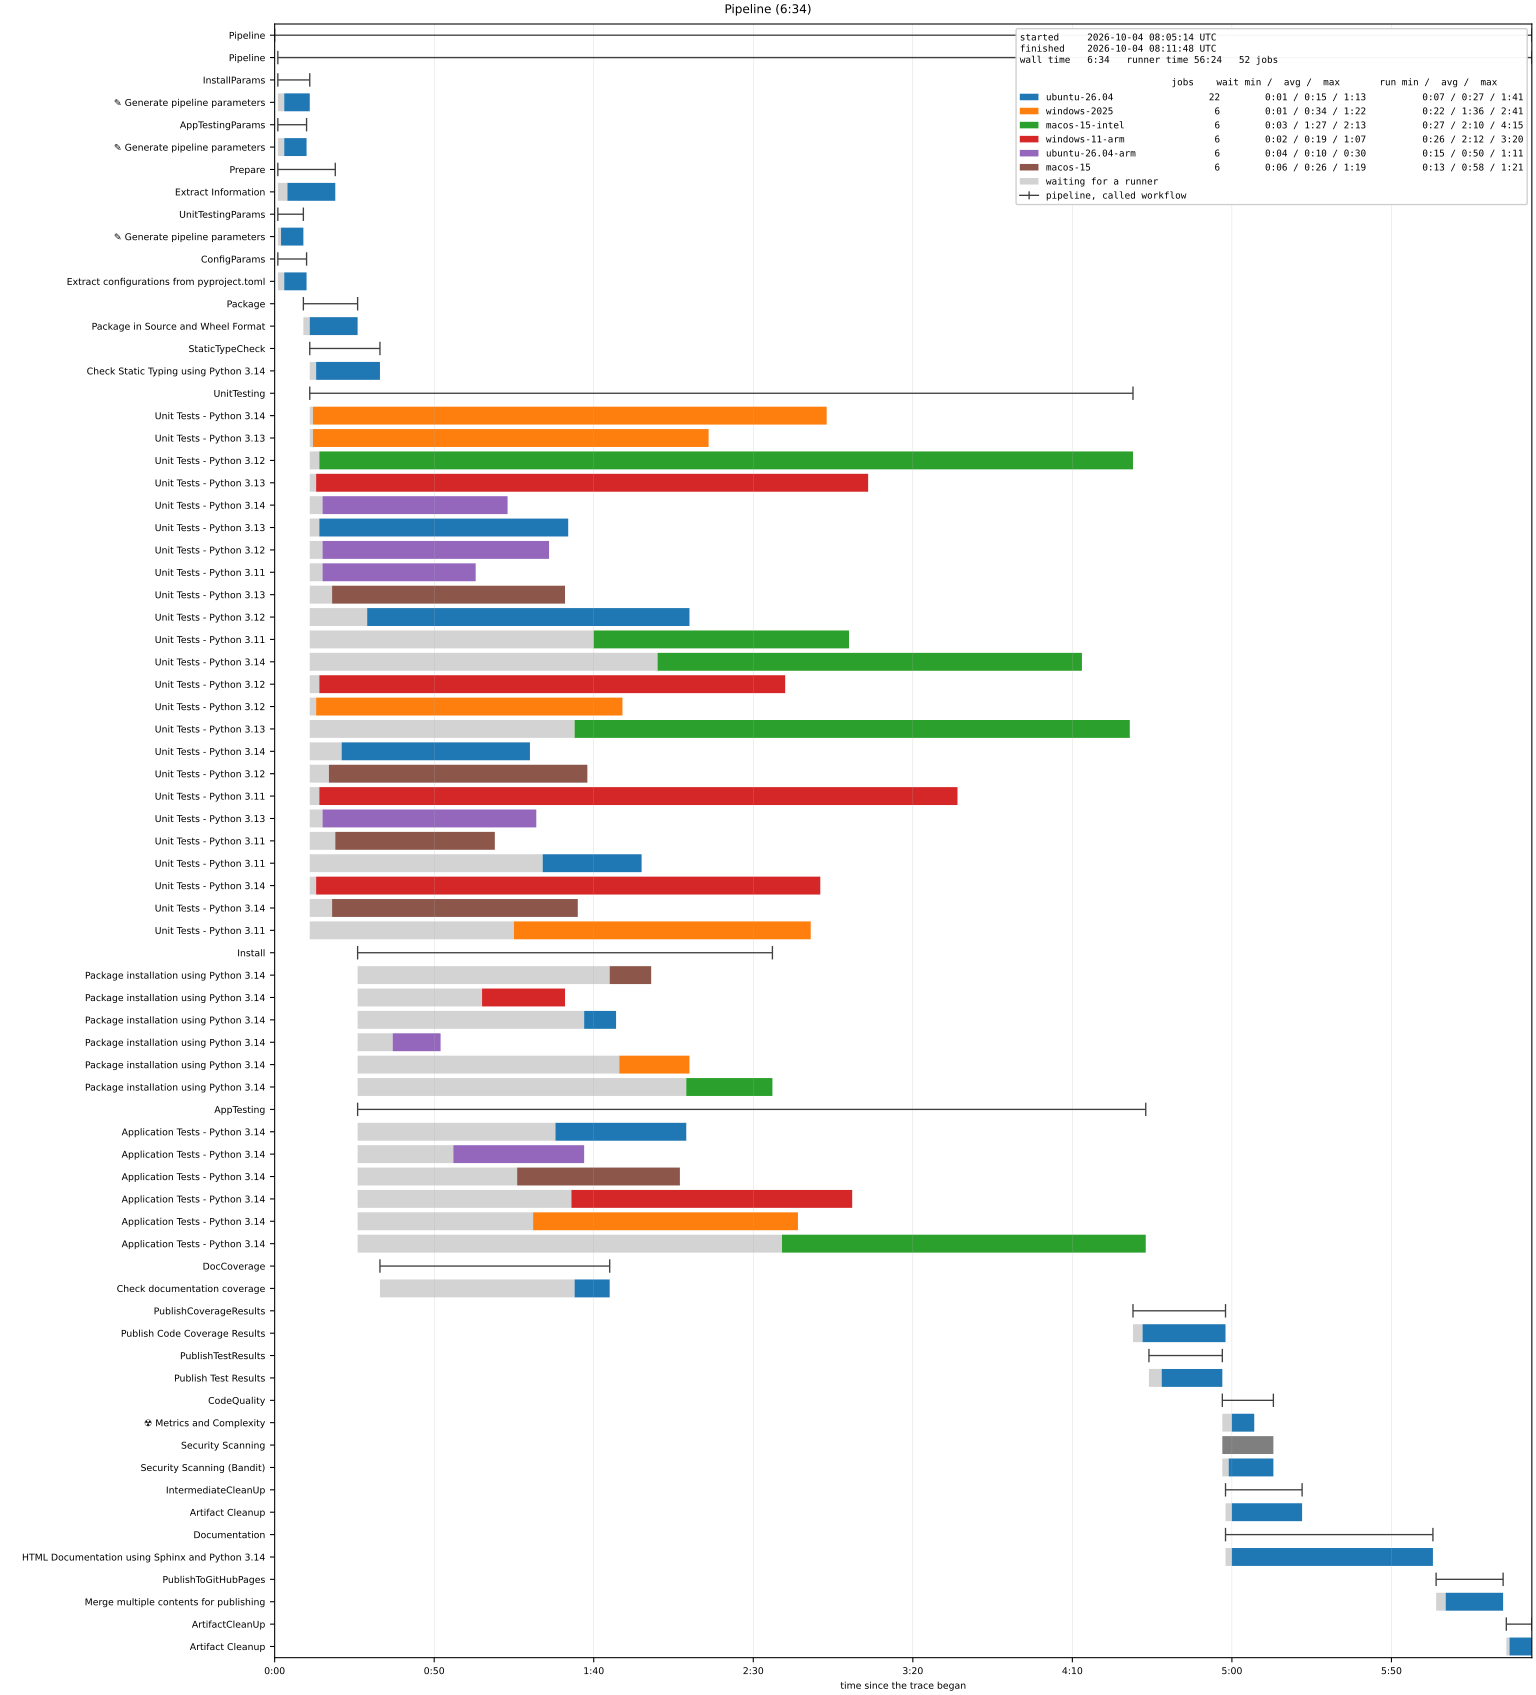
A run of pyTooling.GitHub’s own pipeline (run 37187783003), drawn as above.